You need a spreadsheet of product prices, customer reviews, or job ads. Getting that data can mean copying pages by hand or building a scraper. Even asking ChatGPT for help leaves you with a script you still need to run and troubleshoot.
But with the right tools, ChatGPT can collect web data for you and save the results directly on your computer. Just point it at a URL and describe what you need. For larger tasks or sites that are harder to scrape, you can connect Apify to run a dedicated scraper from the same chat.
This guide covers both approaches using Codex in the ChatGPT desktop app. You’ll start by scraping a few job ads, then expand the collection to build a spreadsheet comparing AI skills employers expect across multiple job roles. Along the way, you’ll learn which tools to enable, what to include in your prompt, how to check the data, and where to find your saved files.
Can ChatGPT scrape websites?
Yes, if the chat has the tools and access the task requires. The model interprets your request, then uses a browser, code, or connected tools to retrieve the data you need.
In the ChatGPT desktop app, both Work and Codex can use the built-in browser to open pages and interact with websites. That browser isn’t available in the Codex CLI or IDE extension, so browser instructions for the desktop app don’t apply to those versions.
What ChatGPT retrieves from a URL depends on the built-in tools available in that chat and what they can access. It may retrieve only part of a page or rely on search results. If the built-in tools can’t collect the data you need, connect a web data tool that supports your target website.
What’s new in web scraping with ChatGPT in 2026?
OpenAI has improved both how Codex extracts web data and where you can use it. The May 21, 2026, browser update made it more effective at extracting structured information from webpages. On July 9, 2026, Codex joined Chat and Work in the ChatGPT desktop app, bringing its coding tools into the same app.
Together, these tools let Codex open pages, collect fields, and organize the results in the same workflow.
Which ChatGPT mode should you use?
The ChatGPT desktop app includes Chat and Work, alongside Codex. For web scraping, here’s where each fits:
| Mode | What you can use it for |
|---|---|
| Chat | Talk through what you want to collect, ask questions, and use the tools enabled in your chat. |
| Work | Gather information from websites, files, and connected apps, then turn it into a report or spreadsheet. |
| Codex | Write and run code to collect, clean, or organize data. |
This tutorial focuses on Codex. Just describe what you need in plain language, and it can write and run the code for you. To follow along, download the ChatGPT desktop app and create an Apify account.
You’ll scrape public Greenhouse job boards to answer one question:
What AI skills do employers in my field actually want me to demonstrate?
For this example, you’ll examine AI specialist roles from four employers. You’ll collect full job descriptions, identify the skills they request, and use supporting excerpts and source links to check each finding.
You can apply the same process to a different field by choosing relevant employers and adjusting the role criteria.
How to scrape websites with ChatGPT: step by step
Start with five postings to check the output, then expand the collection and build your skills spreadsheet.
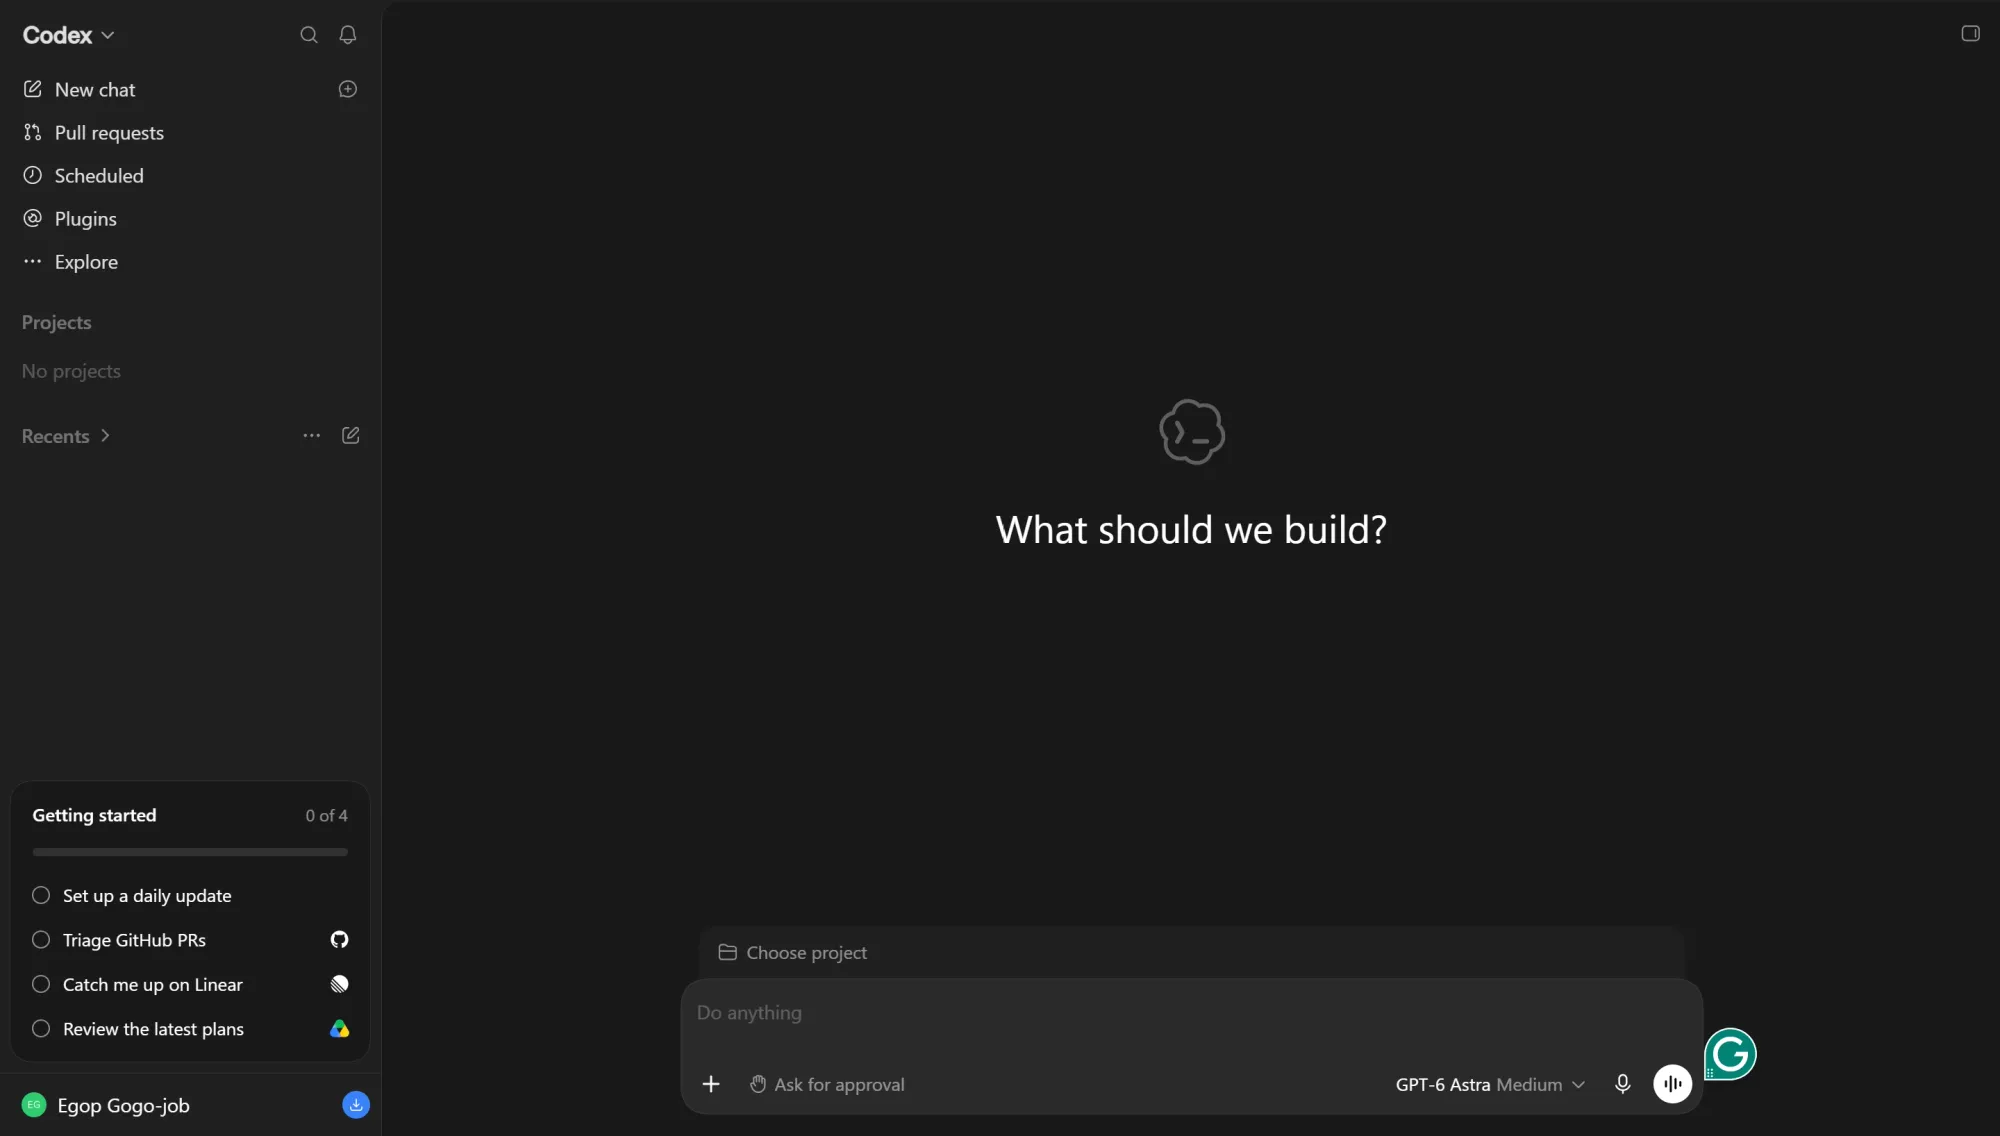
Step 1: Set up Codex in the ChatGPT desktop app
- Download or update the ChatGPT desktop app, then open it and sign in.
- Select Codex from the menu in the top-leftcorner and click New chat.
- Open the model menu and select GPT-6 Astra if it’s available, or keep the model your account offers. Start with the default reasoning effort.
- Create a folder named
chatgpt-scraping-pilotin Downloads to keep your saved files together. If Codex asks you to choose a working folder, select it.
Step 2: Collect five job postings with built-in tools
Start with five postings so you can check the results before collecting more. Paste this prompt into the same chat:
Open https://job-boards.greenhouse.io/gusto and collect the first
five distinct job postings in the board's current default order.

Use your built-in tools. Do not use an external
scraping service.

For each job, collect:
- Company name, company slug (gusto), and job posting ID
- Job title and department
- Location exactly as stated
- Full job description as plain text
- Source URL
- Publication date, if explicitly available
- Last update date, if explicitly available
- Collection time in UTC

Retrieve the actual descriptions. Do not substitute search snippets.
Keep publication dates separate from update dates. Use null for
missing JSON values and empty cells for missing CSV values.

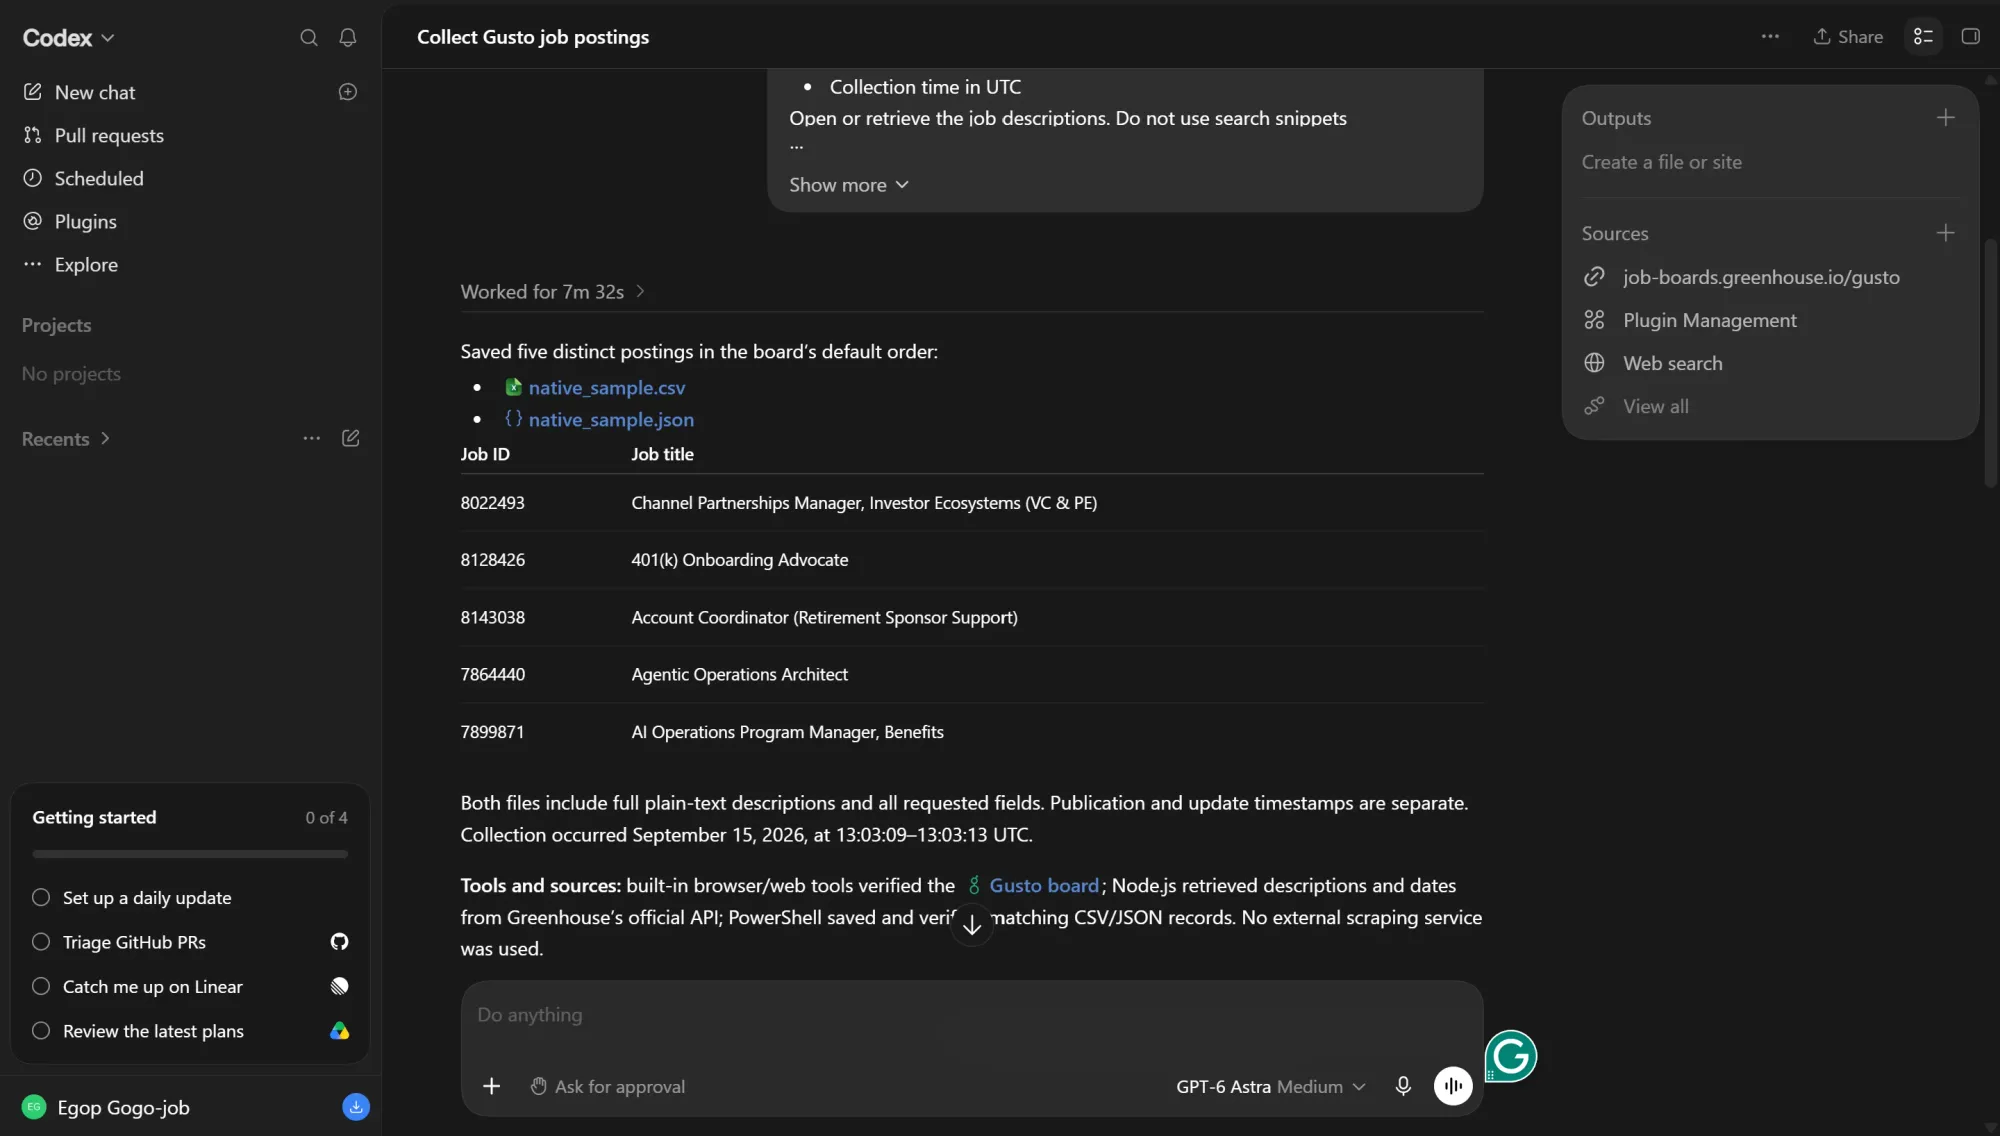
Save native_sample.csv and native_sample.json. Provide working
file links, the full saved paths, and a short preview.
Report the tools and data sources used and any incomplete records.
If access fails, report the failure without inventing data.
The prompt tells Codex where to look, how many records to collect, which fields to include, and how to save the results. It also explains what to do when information is missing. You can adapt those instructions to collect product prices, reviews, or another type of public data.
In my test, Codex returned five postings with descriptions. The prompt keeps publication and update dates in separate fields.
Step 3: Open the files and check the output
- Download both files and confirm that each contains five distinct postings with descriptions.
- Open the source links for at least two records. Compare the title, location, and full description with the saved data.
If the folder you created is empty, look at the full path ChatGPT returned. During my test, Codex saved files in its own task output folder. It didn’t automatically put them in the folder I created in Downloads. Open the returned file links, then save or copy the files into your pilot folder.
The next steps will show you how to connect Apify and expand data collection across several employers.
null values.Step 4: Connect Apify to ChatGPT
Apify Actors are ready-made programs that collect data or carry out other tasks. The Apify MCP server uses Model Context Protocol (MCP) to let ChatGPT find an Actor, inspect its inputs, run it, and retrieve the results.
In the desktop app:
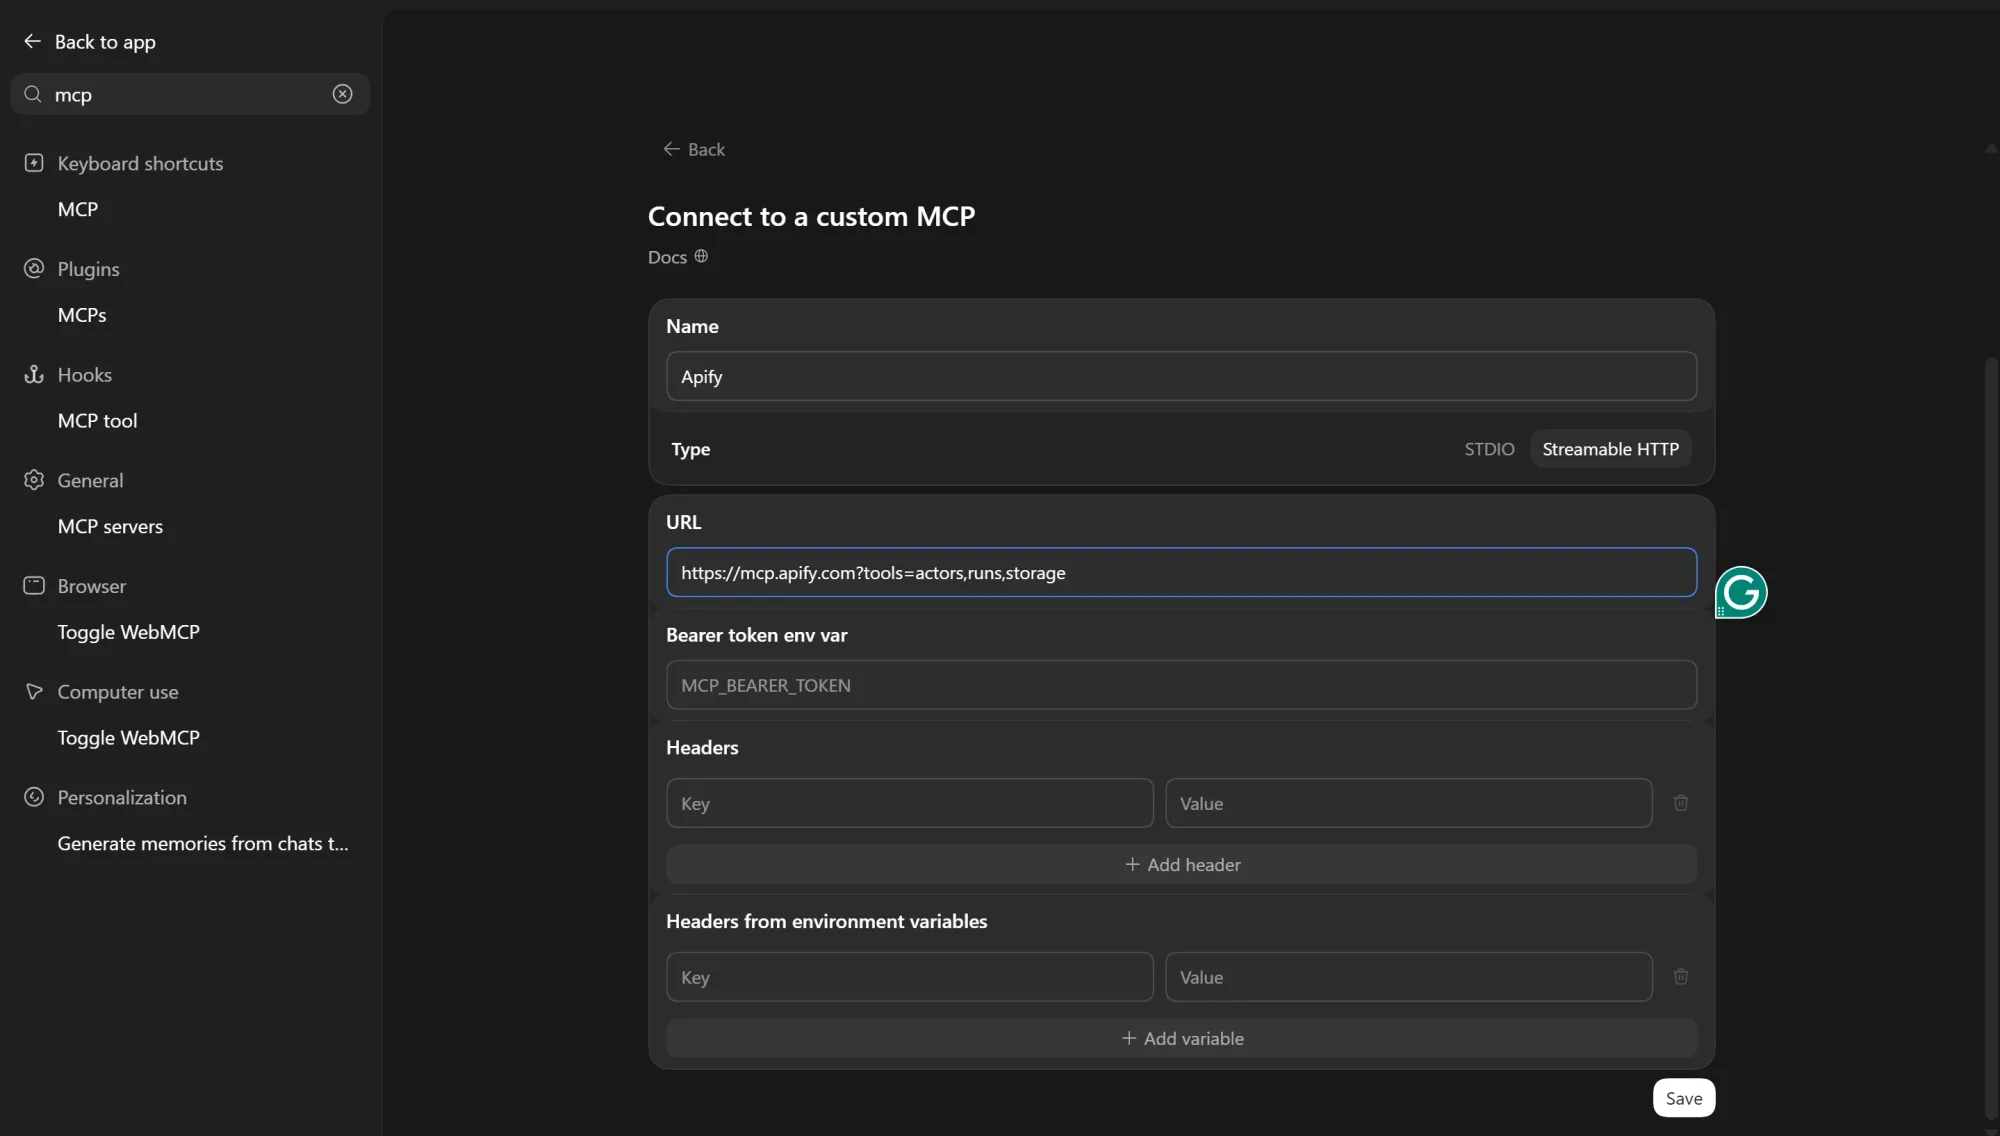
- Open Settings, then select MCP servers.
- Select Add server and name it
Apify. - Set the connection type to Streamable HTTP to reveal the URL field.
- Paste this address:
https://mcp.apify.com?tools=actors,runs,storage
- Save the server, then select Authenticate, sign in to Apify, and approve the requested access.
- Open a new Codex chat.
- Type
/mcpin the message box to check the connected servers.
The URL enables tools for Actors, runs, and storage. Apify sign-in uses OAuth, so you don’t need to paste an API token into the chat.
Step 5: Inspect an Actor and test five records
For this tutorial, I used Greenhouse Jobs Scraper from Apify Store. It retrieves Greenhouse job data through the public Job Board API.
Before starting a paid run, ask ChatGPT to check that the Actor supports the fields and settings you need:
Use the connected Apify tools to inspect:
automation-lab/greenhouse-jobs-scraper

Do not start a run yet.

Confirm its current input schema, pricing, output fields, and
support for Gusto's public board with full descriptions.

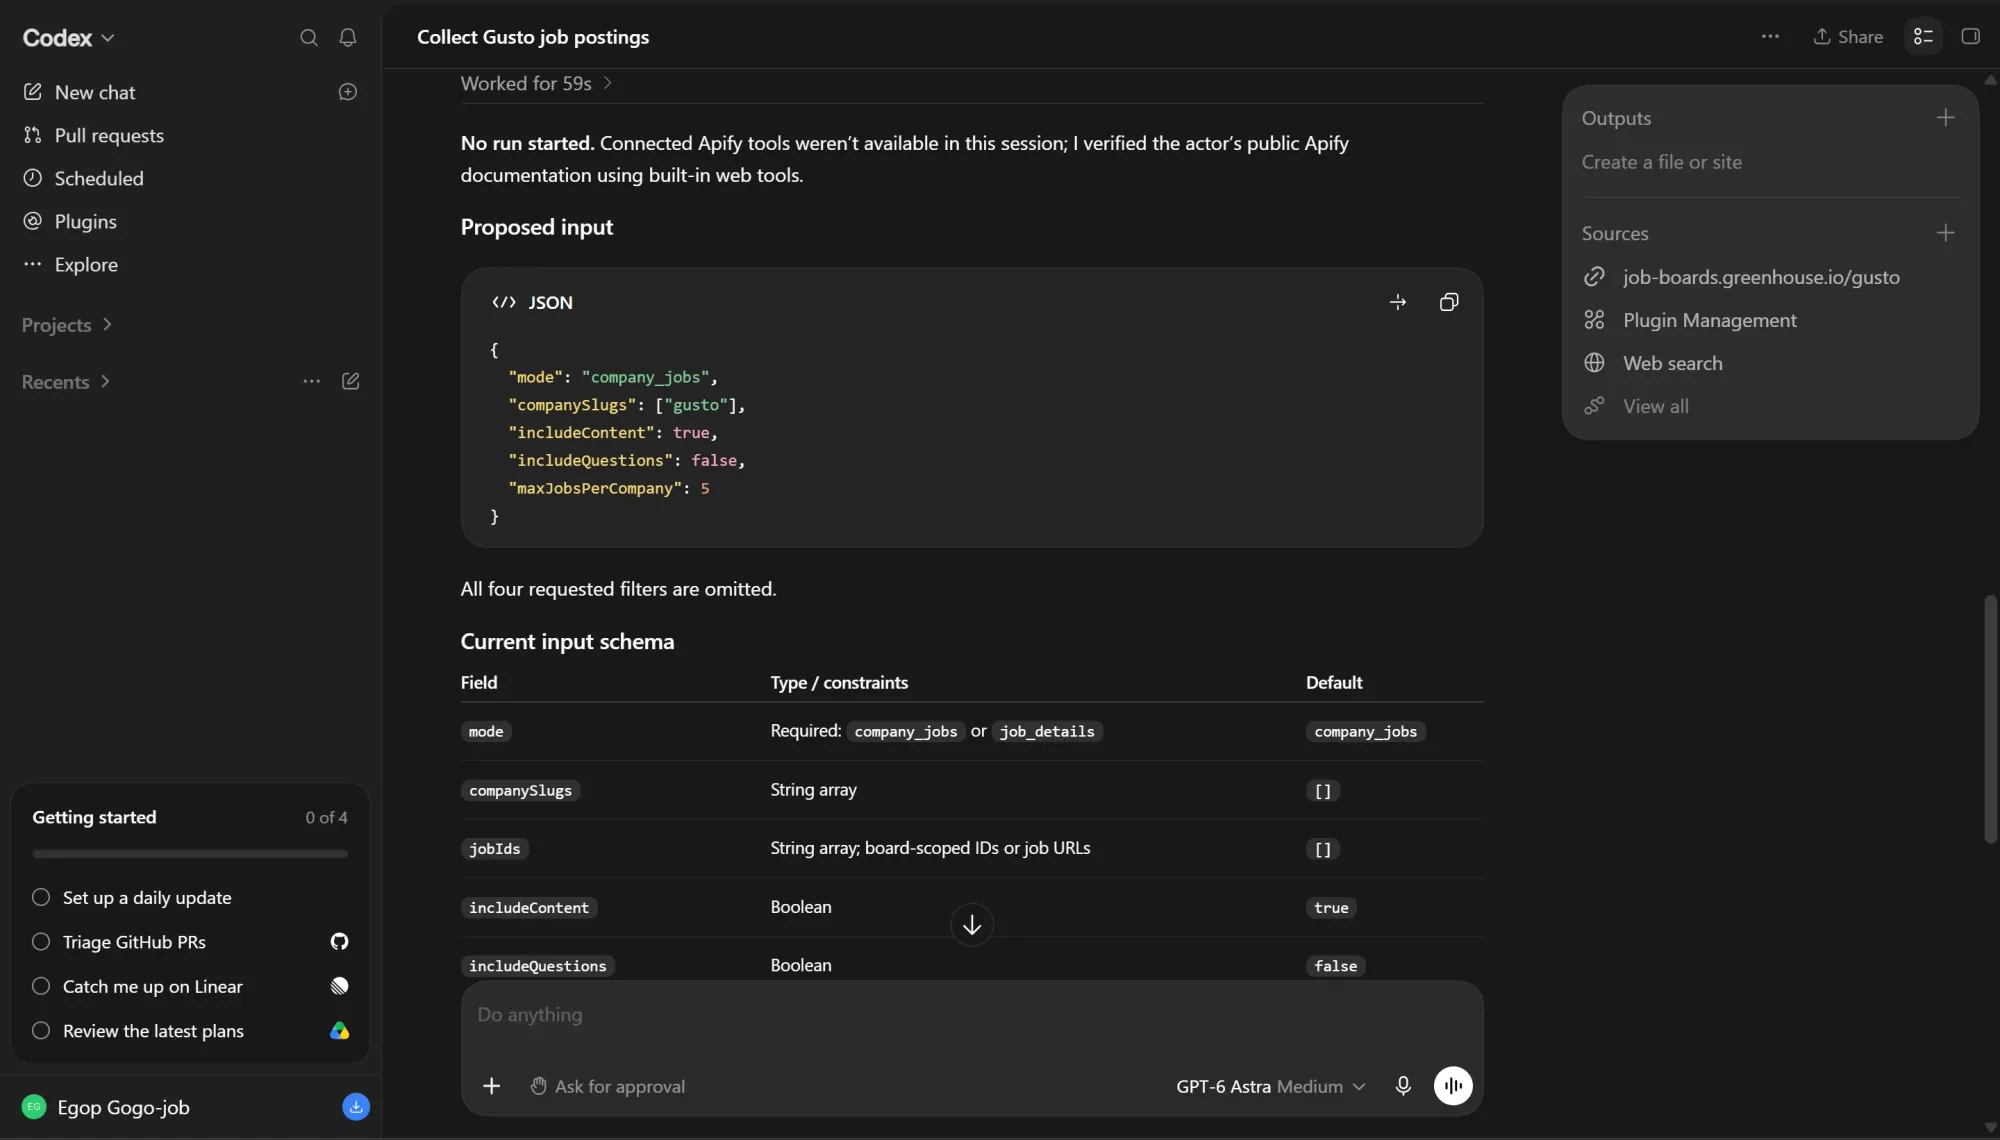
Prepare this input, with all filters unset:
{
  "mode": "company_jobs",
  "companySlugs": ["gusto"],
  "includeContent": true,
  "includeQuestions": false,
  "maxJobsPerCompany": 5
}

Show the proposed input and estimated charge for my account.
Report which connected Apify tools you used.
A company slug is its Greenhouse board identifier, such as gusto. includeContent requests each job’s full description in HTML. Leave includeQuestions set to false, since this tutorial doesn’t need application-form questions. The job limit applies to each company separately.
At the published Free plan rate, five saved jobs would cost $0.02: a $0.01 start fee plus $0.002 per job. Still, check your account's current rate before running the Actor.
Once you’re satisfied with the input and estimated cost, send:
Run the five-job sample using the input we just inspected.
Start exactly one run of automation-lab/greenhouse-jobs-scraper.

Use connected Apify tools for collection. You may use code to
process the returned records and create files.

Return the run ID and dataset ID. Follow that same run until it
finishes. If a tool times out, check the existing run rather than
starting another.

Retrieve every dataset item, following pagination if needed.
Save the unchanged records as apify_sample_raw.json.

Create apify_sample.csv with the same fields as the native sample.
Convert HTML descriptions to plain text without summarizing.
Use the actual UTC retrieval time as the collection time.

Provide file links and full paths. Report final status, dataset
and retrieved counts, distinct job IDs, missing or incomplete
descriptions, actual charge if available, and tools used.
Do not start any further runs.
My run returned five distinct postings. Your sample may contain fewer if the board has fewer postings available.
Step 6: Collect postings from multiple employers
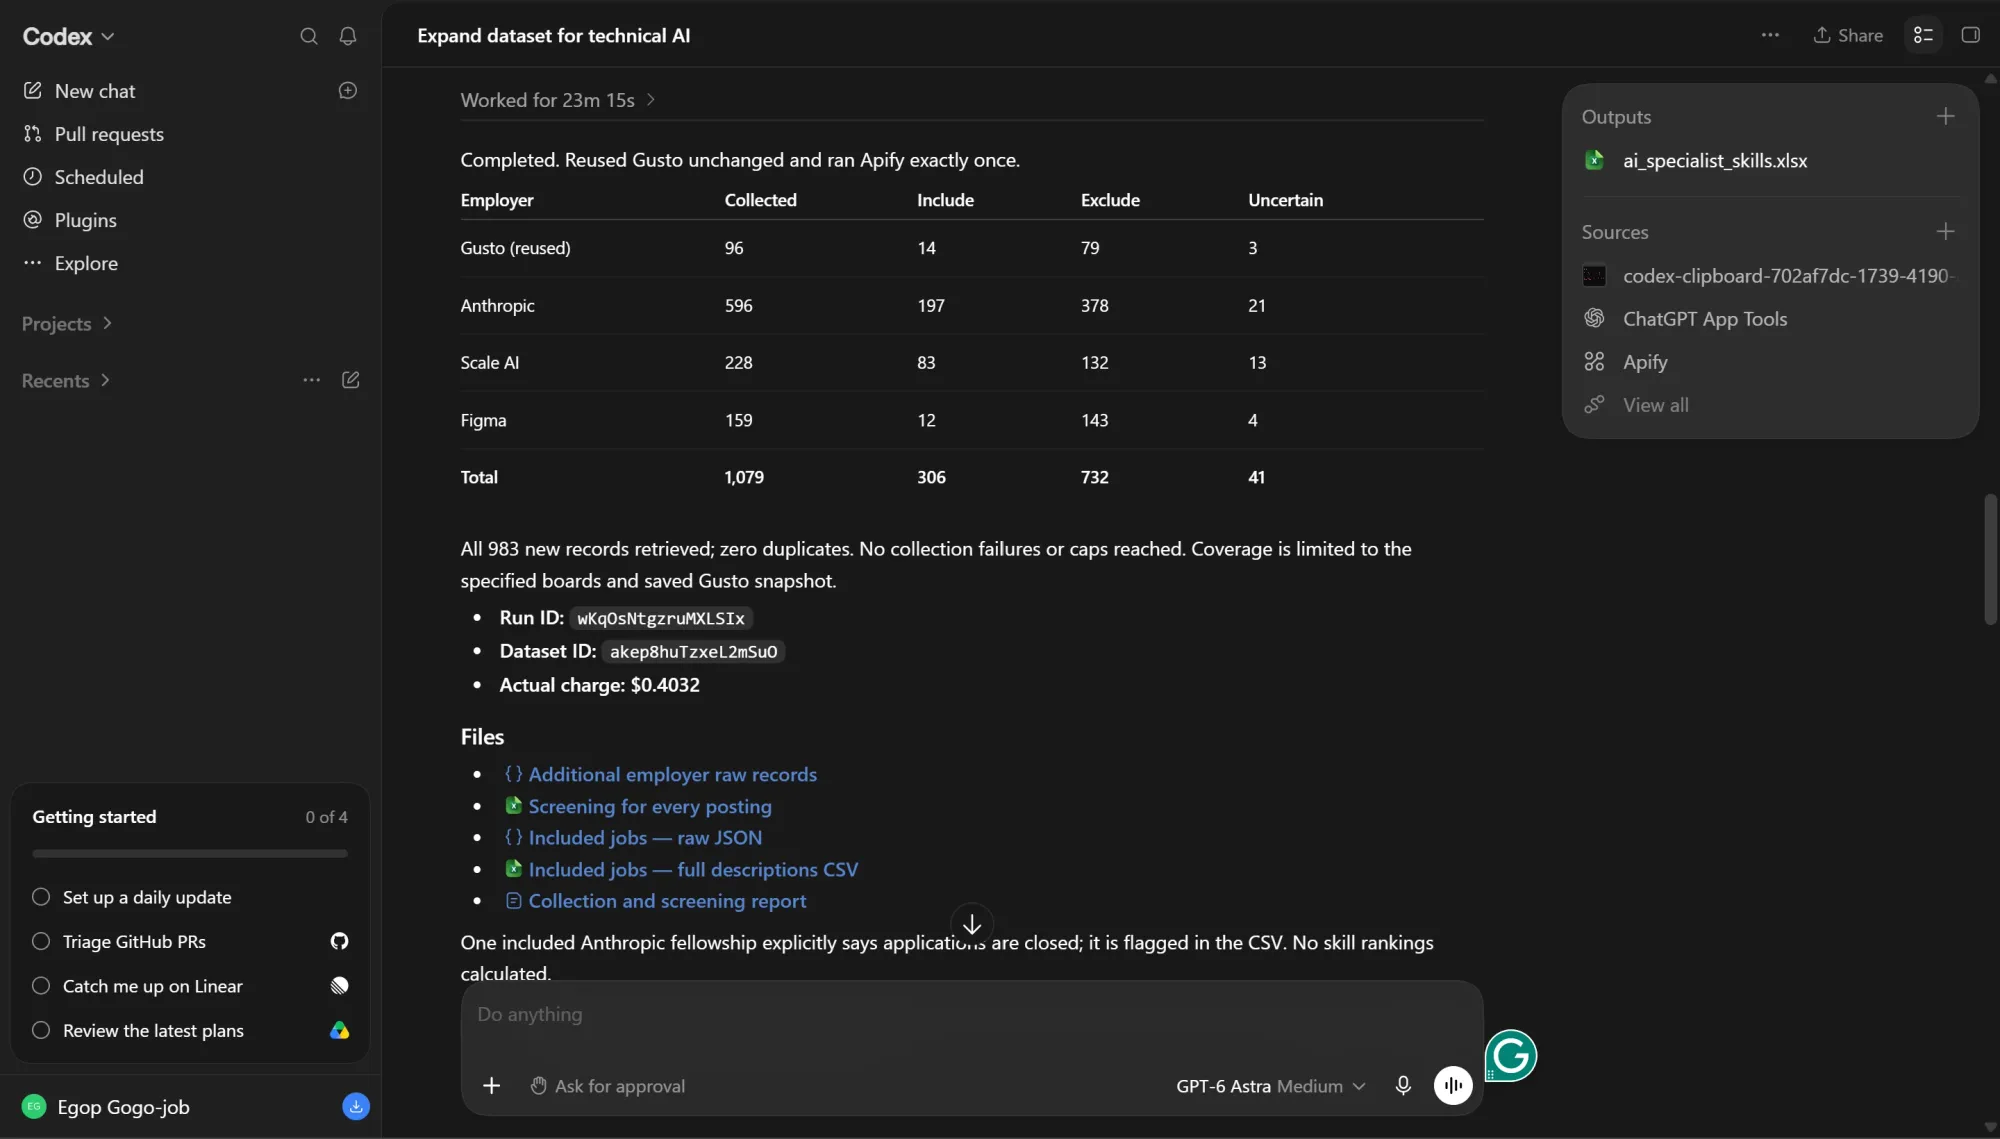
I started with job ads from Gusto, then added Anthropic, Scale AI, and Figma in a separate run. Altogether, those collections produced:
| Employer | Collected postings |
|---|---|
| Gusto | 96 |
| Anthropic | 596 |
| Scale AI | 228 |
| Figma | 159 |
| Total | 1,079 |
For a fresh collection, the Actor supports passing all four company slugs in one run. Also, just as a precaution, ask ChatGPT to inspect this larger input and estimate the cost before you authorize it:
Prepare one fresh run of automation-lab/greenhouse-jobs-scraper
with this input. Do not start it yet.

{
  "mode": "company_jobs",
  "companySlugs": ["gusto", "anthropic", "scaleai", "figma"],
  "includeContent": true,
  "includeQuestions": false,
  "maxJobsPerCompany": 1000
}

Leave all filters unset. Confirm the current pricing and estimate
the charge for this account. State the maximum record count
allowed by this input and the charge if that maximum is reached.
The limit allows 1,000 jobs per company, or 4,000 across the four employers. At the Free plan rate above, that would cost $8.01, including the start fee.
Leave keyword filters off for now. They search both titles and descriptions, so a general company statement about AI could bring in unrelated jobs. You’ll identify AI specialist roles from the full descriptions later.
If the settings and estimated cost look right, send:
Run the larger collection with the input we just reviewed.
Start exactly one run and return its run ID and dataset ID.
Follow that same run to completion. Do not launch a replacement.

Retrieve all dataset records through connected Apify tools,
following pagination. Keep this collection separate from the
five-job sample; do not append the sample records.

Save unchanged records as jobs_raw.json and create jobs.csv with
the same fields as the sample and full plain-text descriptions.

Report collected and retrieved counts by employer, unique
company-slug/job-ID pairs, duplicates, missing descriptions,
failures, caps, actual charge, and UTC start and finish times.
Provide file links and full saved paths.
Do not claim complete coverage without supporting evidence.
Your counts will differ as employers add and remove postings. A record limit is a ceiling, so receiving fewer records doesn't mean the task failed.
Step 7: Validate the data and export a copy from Apify
Before analyzing the data, check that ChatGPT saved the Actor’s results correctly. You can also download a copy directly from Apify:
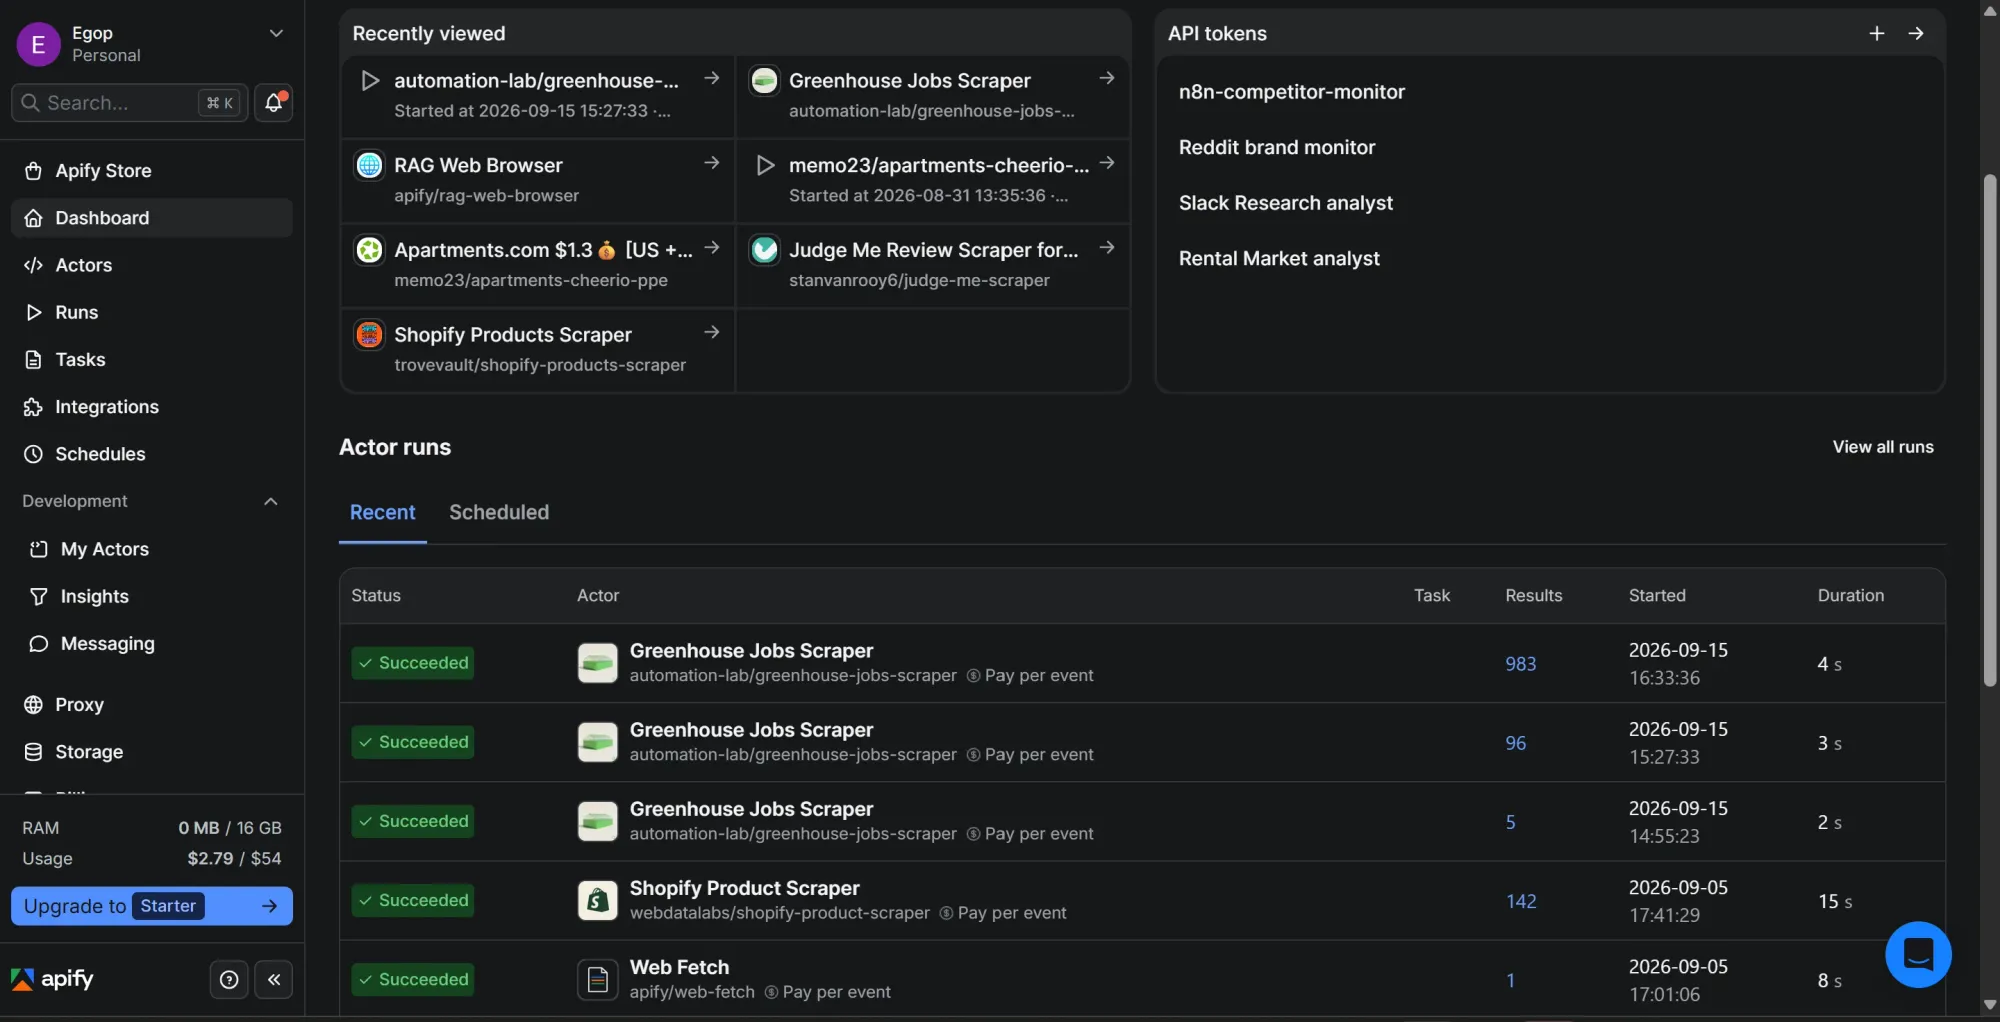
- Open Apify Console, go to Runs, and select the returned run. Inspect the input, output, and log to confirm the companies and limits match your request.
- Compare the dataset count with the number of records ChatGPT saved.
- Open the dataset and select Export. Download JSON and CSV directly from Apify. Excel and other export formats are also available.
- Check a few descriptions against their source pages, including the final paragraphs, to see whether any text was cut off.
The direct export keeps the Actor’s fields and HTML descriptions, so it may look different from the CSV ChatGPT formatted.
My expanded run returned 983 new records, which were combined with the 96 Gusto records saved earlier.
The review also found an explicitly closed fellowship. So a successful scrape captures what the source says; it doesn’t confirm that every advertised opportunity is still open.
Step 8: Turn the job data into a skills spreadsheet
Now you'll use the collected descriptions to identify the skills these four employers ask for in their job roles.
If you’d like to investigate a different field, change the role criteria in the screening prompt below and the question in the analysis prompt to match.
First, screen the records:
Use jobs_raw.json. Do not scrape again. Preserve the source file.

Classify each posting as Include, Exclude, or Uncertain using
its full description.

Include roles where AI/ML research, development, training,
deployment, evaluation, or the supporting technical
infrastructure is central. Keep technical product roles in
their own role family.

Exclude incidental AI tool use, general company statements,
nontechnical roles at AI companies, general talent pools,
and postings explicitly stating applications are closed.

Keep unclear or incomplete cases Uncertain. Record the company,
job ID, title, source URL, decision, reason, and exact evidence.

Review included and uncertain cases, plus a reproducible sample
of 20 exclusions per employer. Investigate recurring errors.
Record changed decisions and the scope of the review.

Save ai_role_screening_reviewed.csv, a review log, and
ai_jobs_reviewed_raw.json containing unchanged included records.
Report the final counts by employer and any review limitations.
My review produced 325 included postings, with 39 uncertain cases kept outside the analysis. The set contained 17 Gusto, 202 Anthropic, 92 Scale AI, and 14 Figma postings.
Next, ask ChatGPT to analyze that shortlist:
Use ai_jobs_reviewed_raw.json and the screening review notes.
Do not collect new data or change the source files.

Answer: What do these employers ask AI specialists to know
and demonstrate?

Read the full descriptions. Extract specific skills, tools,
and expected work. Separate required qualifications, preferred
qualifications, responsibilities, and ambiguous wording.
Retain exact excerpts and source URLs.

Preserve alternatives such as “PyTorch or TensorFlow.” Do not
turn every listed option into a mandatory requirement.
Exclude company boilerplate and ambiguous evidence from counts.

Create ai_specialist_skills.xlsx with four sheets:
- Jobs: one row per company slug and job ID, with role family,
  stated seniority, location, source URL, and limitations.
- Skill evidence: skill, named tool, expected work, classification,
  exact excerpt, employer, job ID, and source URL.
- Summary: distinct postings and employers mentioning each skill,
  separate classification counts, and percentages with clear
  denominators. Count each posting once per skill overall.
- Role comparison: skills within each role family and stated
  seniority group, with the size of each group shown.

Export Jobs and Skill evidence as CSV files. Verify the counts
and that excerpts occur in the saved descriptions.
Provide file links, a short findings preview, and limitations.
Keep any learning suggestions separate from employer statements.
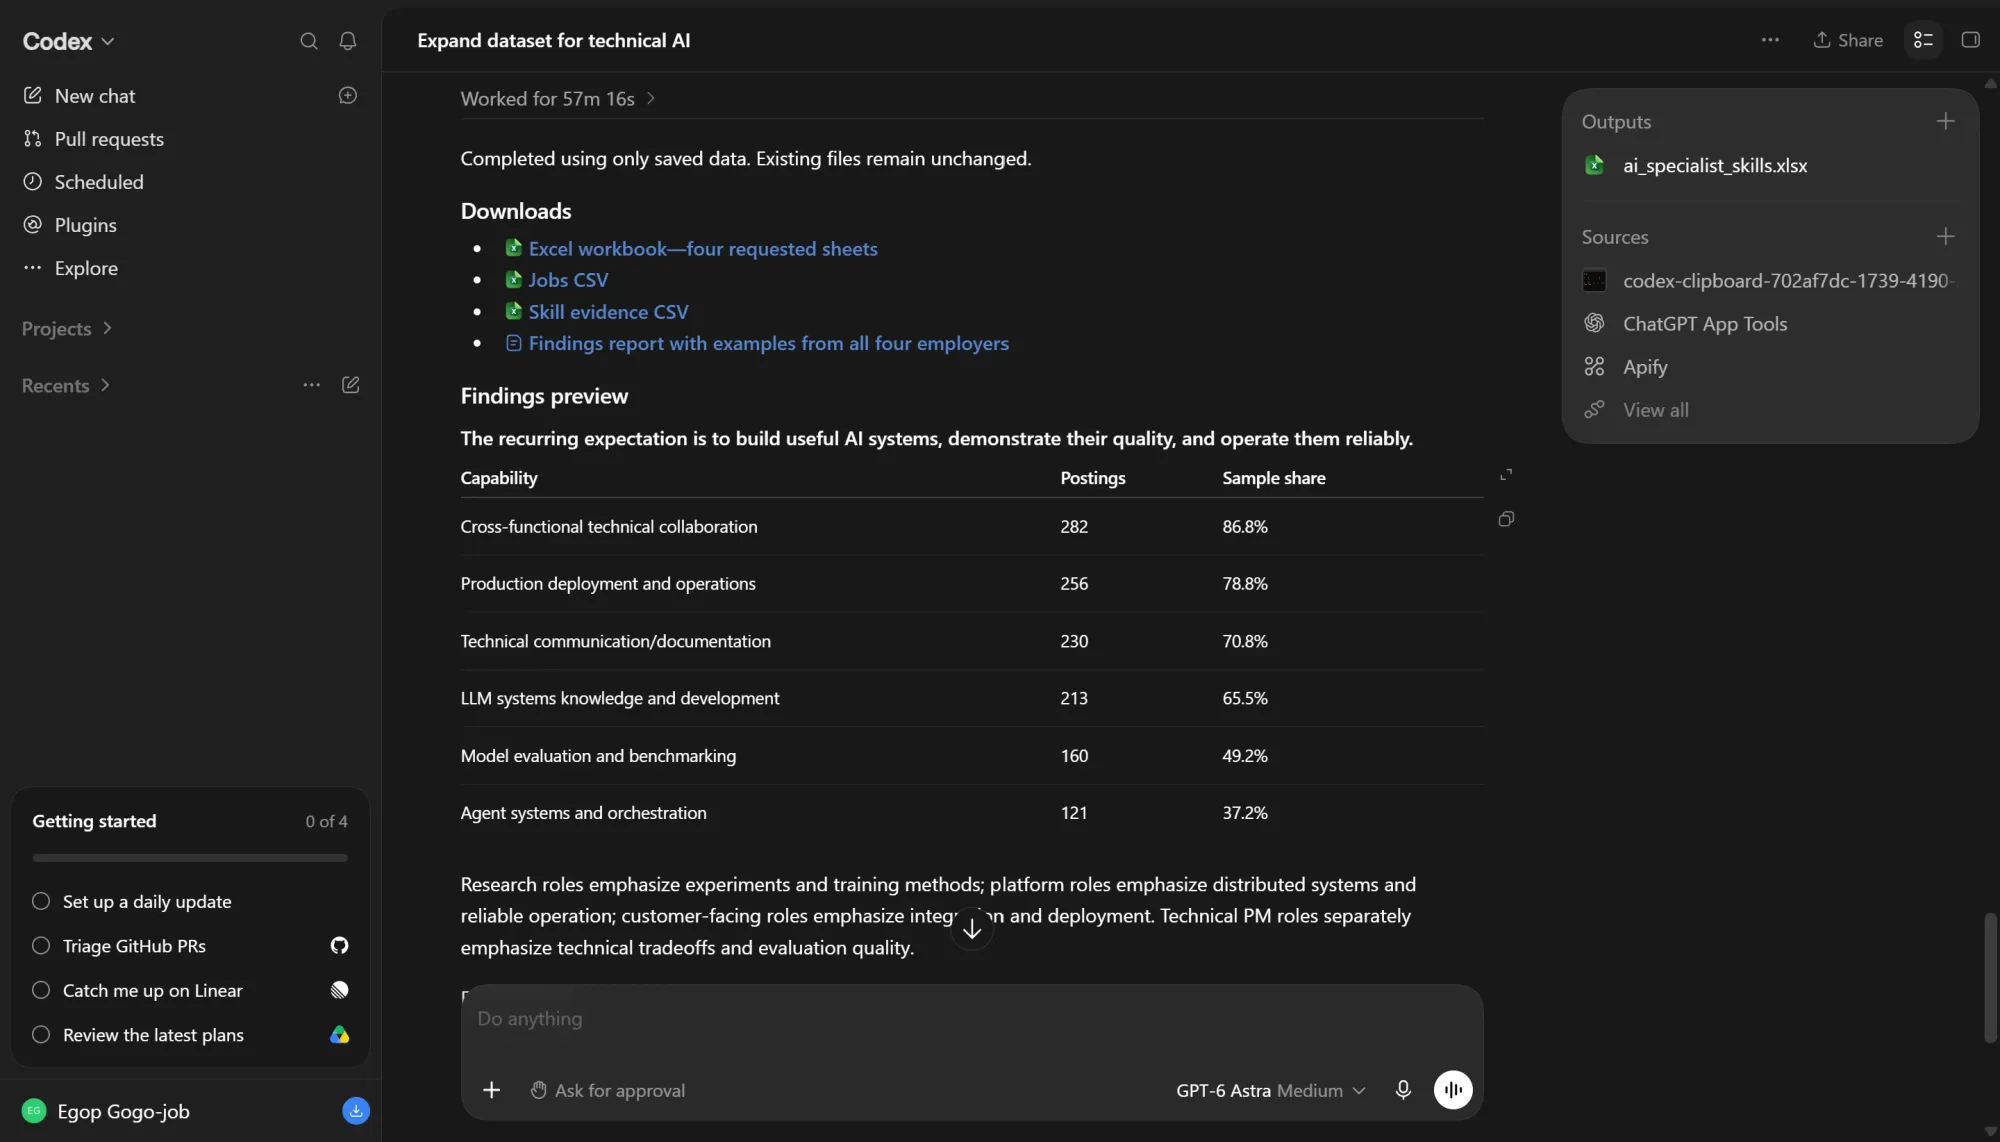
The workbook links each finding to a supporting excerpt and source URL. Across the 325 included AI specialist postings from Gusto, Anthropic, Scale AI, and Figma, my analysis found these capability mentions:
| Capability | Postings | Share of the 325-posting sample |
|---|---|---|
| LLM systems knowledge and development | 213 | 65.5% |
| Model evaluation and benchmarking | 160 | 49.2% |
| Agent systems and orchestration | 121 | 37.2% |
| Model training and fine-tuning | 79 | 24.3% |
These counts include required qualifications, preferred skills, and job responsibilities. They don’t mean every skill was a mandatory entry requirement. A posting can mention several capabilities, so these percentages don’t add up to 100%.
The results describe four employers. Anthropic and Scale AI account for 294 of the 325 included postings (90.5%), so the findings are weighted toward those companies. They don’t represent the overall AI job market. Counts refer to postings; similar roles advertised in different locations may appear separately.
The job descriptions show how requirements and responsibilities differ. Gusto’s Agentic Operations Architect asks for practical experience with agents and states that “conceptual familiarity is not sufficient at this level.” Figma’s AI Applied Scientist lists both experience training models and responsibility for building evaluation systems.
Use the Role comparison sheet to see how requested skills differ across research scientists, infrastructure engineers, technical product managers, and other AI role families in this sample.
When should you use a dedicated scraper?
If you only need a few records, ChatGPT’s built-in tools may be enough. A dedicated scraper like an Apify Actor is useful when you need to collect data regularly or want a scraper built for a specific website.
You can run it again, check previous runs, and download your saved results outside ChatGPT.
This Greenhouse example uses a public API. It doesn’t demonstrate bypassing bot protection or scraping private websites. For another source, search Apify Store for a suitable Actor, check its supported fields and pricing, and test a small sample.
Frequently asked questions
Can ChatGPT scrape pages behind a login wall?
Yes, in some cases. After you sign in through the desktop app’s built-in browser, Codex can collect data from pages your account can access. Some websites still block automated scraping, even after you log in.
Can I export scraped data in CSV, JSON, or Excel through ChatGPT?
Yes. This tutorial produced CSV and JSON files of the scraped data, plus an Excel workbook for the analysis. You can download the files from ChatGPT or export datasets directly from Apify in all three formats.
Can I use the same prompt for any website?
You can reuse it as a template, adjusting the source, fields, record limit, checks, and file format to your task. The collection tool must also support the website. The Actor used here is built for Greenhouse boards, so changing the URL won’t make it scrape an unrelated platform.