Ask a chatbot a question, and you get an answer in seconds. But where does AI get its information? LLMs learn patterns from large datasets during training, including text, code, images, and audio.
Because training ends before a model is deployed, its knowledge doesn’t include recent events. This is known as a knowledge cutoff. To address that limitation, many AI systems use data retrieval tools to search for up-to-date information.
This article explains the two main ways generative AI gets information: training and retrieval. You’ll learn where training data comes from, how web data is collected, how retrieval provides fresh information, and which sources ChatGPT, Claude, and Google’s AI rely on to reply to your prompts.
Training data vs. real-time information in AI systems
AI systems obtain information in two main ways:
- Training on static datasets: A machine learning model learns language patterns by adjusting its internal parameters while processing large datasets. This gives it the ability to generate content.
- Live data retrieval: When you ask a question, the system fetches contextual information from external sources and uses it to generate an answer.
Since training data covers a specific period, an AI model inherently has a knowledge cutoff. This means its learned knowledge can’t include information published after a certain date. Without access to external sources, the model can’t reliably answer questions about recent developments.
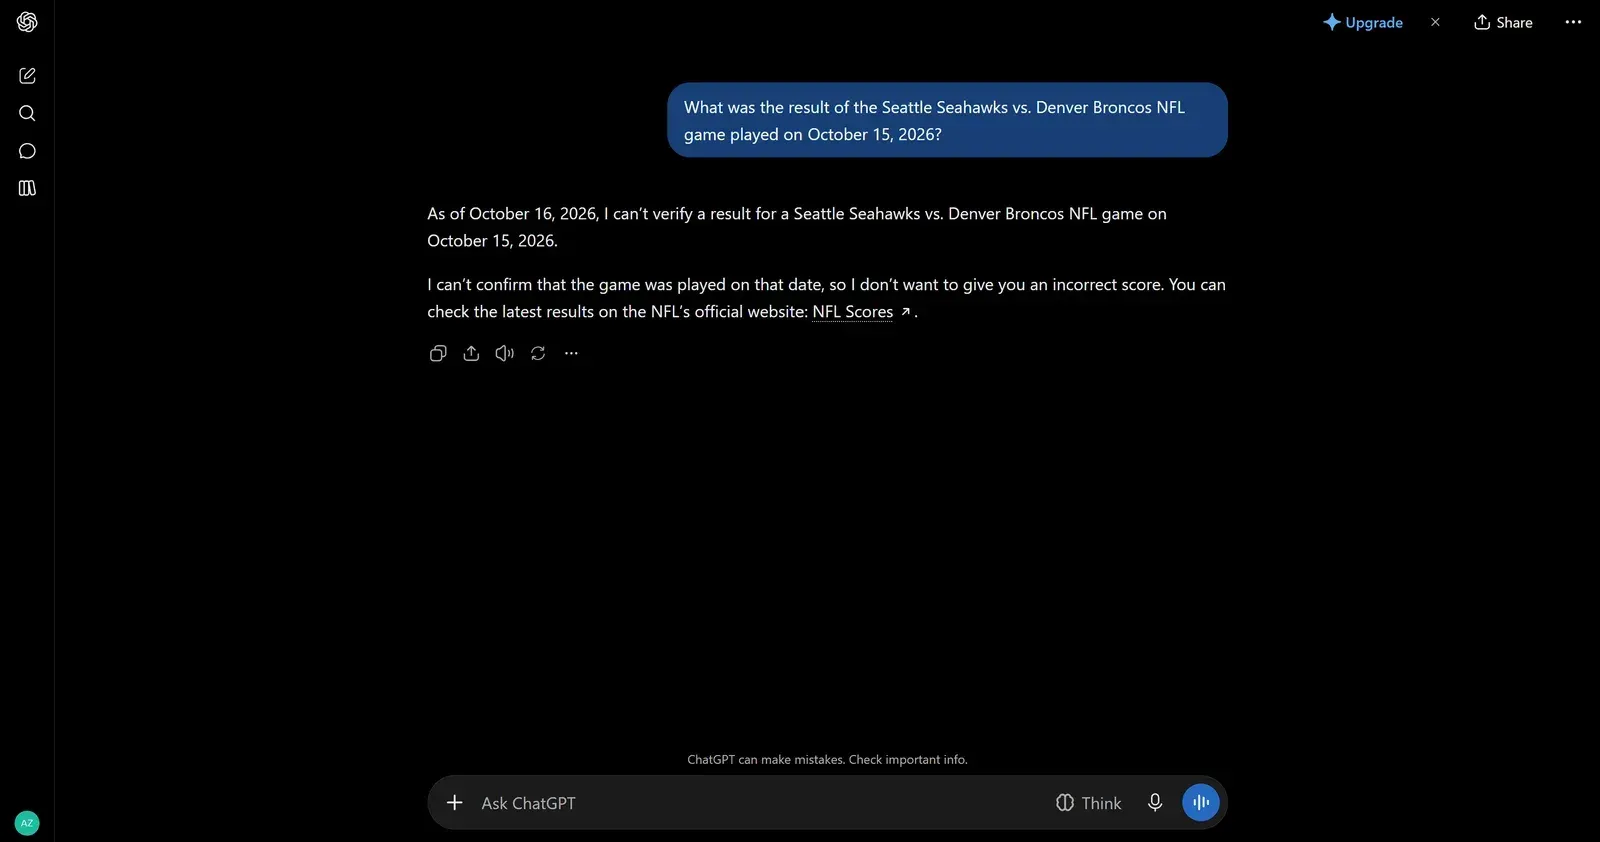
More dangerously, it may generate a plausible but incorrect answer, known as a hallucination.
Retraining models frequently can update their knowledge, but it requires additional data, time, and resources. A more cost-effective and flexible alternative is to let AI applications retrieve information from external sources when a user asks a question.
One common approach is RAG (Retrieval-Augmented Generation). The system searches a knowledge base or other data sources, retrieves matching passages, and adds them to the context provided to the model. The model then uses this information to generate an answer grounded in the retrieved content.
In this case, answer quality depends on the relevance, accuracy, and freshness of the retrieved data. Tools such as QuillBot AI Search use web search to provide answers with inline citations, allowing users to verify the information against the original pages.
Where AI training data comes from
AI training data comes from a mix of sources, which shape what a model knows, how well it generates content, and where its knowledge gaps lie. If you’ve ever wondered, “Where do LLMs get their data?” here are the main sources:
| Data type | Sources | Strengths | Limitations |
|---|---|---|---|
| Web data | News sites, forums, social media, code repositories, and other websites | Large scale and broad topic coverage | Noisy, duplicated, and inconsistent in quality |
| Books and academic papers | Digitized books, self-published works, journal articles, preprints, and research repositories | Long-form, well-structured content and specialized knowledge | Copyright restrictions, outdated information, and dense or highly specialized language |
| Synthetic data | Text, images, and other content generated by AI models | Fills data gaps and allows greater control over training examples | Can reproduce or amplify errors and biases in the models that generate it |
| Licensed and proprietary data | Datasets purchased or licensed from providers | Defined usage rights, potentially higher quality, and access to specialized data | Often expensive and limited to the data available from providers |
Web data
Where does AI get its information from? Mostly, the web. It’s one of the largest data sources, with estimates putting the total at over 175 zettabytes (175 billion terabytes). The indexed web alone contains at least 3.98 billion pages.
One major source of web data for AI is Common Crawl, a nonprofit that maintains a free, open archive of web data and publishes new crawls regularly. A 2024 Mozilla Foundation study found that at least 64% of 47 LLMs published between 2019 and October 2023 were trained on Common Crawl data. For instance, OpenAI’s GPT-3 presentation paper shows that a filtered version of Common Crawl accounted for 60% of the model’s weighted training mix.
The web also provides specialized datasets. GitHub hosts code repositories, while Stack Overflow contains programming questions and answers. Reddit, X, social media, and online forums provide discussions and conversational text.
Audio and video can also contribute to training datasets. Speech recognition tools can convert public videos, lectures, podcasts, and recorded meetings into text. Video summarization tools can also produce transcripts and summaries from recordings.
Web data offers a broad range of topics, writing styles, and perspectives, but it isn’t ready for training as collected. Pages can contain duplicate content, irrelevant text, spam, or inaccurate information. AI developers must filter, clean, and process this data before using it to train a model.
Books and academic papers
Books provide examples of longer, structured, carefully edited writing. The original GPT model was trained mainly on BookCorpus, a collection of more than 7,000 unpublished books.
GPT-3 used two additional book-based datasets, Books1 and Books2, which each accounted for 8% of its weighted training mix. Recently, AI companies have also acquired and scanned millions of physical books to build training datasets.
Academic papers, peer-reviewed journals, and scientific publications provide specialized knowledge. These sources offer more reliable information than unfiltered web pages, although their quality still depends on the publication and subject.
Licensed book collections and academic repositories can help address copyright concerns, but they don’t resolve every legal or ethical question about using books to train AI models.
Synthetic data
Synthetic data is text, images, or other content generated by AI and used to train other models. Teams use it to fill gaps in training datasets, balance underrepresented categories, or improve performance in specific domains.
Using synthetic data can reduce reliance on scraped web content and give you more control over training datasets. However, the paper “The Curse of Recursion: Training on Generated Data Makes Models Forget” found that repeatedly training models on AI-generated data can cause them to lose information about the original data distribution. This effect, known as model collapse, can degrade a model’s performance over successive generations.
Plus, synthetic data creates a feedback loop. As more people publish AI-generated content online, future web crawls collect more of it. For example, a writer who drafts text with ChatGPT and refines it using a paraphrasing tool such as GPTinf adds to this pool when they publish the result.
Proprietary and licensed datasets
Proprietary datasets give you an edge in specialized applications such as legal, medical, or financial AI. Companies purchase curated datasets from data providers to improve their models in a specific domain.
Licensed data generally comes with quality guarantees, clearer usage rights, and contractual terms. Yet, it tends to be more limited in scale and significantly more expensive.
The web data collection pipeline: From source to AI
Web data must be gathered at scale and processed before AI models can use it as one of the main sources to learn about the world.
How web crawlers and scrapers discover content
A web crawler starts with a list of seed URLs, fetches each page, and adds the links it finds to a queue. It then visits those links and repeats the process to discover more pages. Next, a web scraper extracts the required content from each page, such as text, headings, metadata, and links.
For effective AI training, you need to collect millions of pages. At this scale, automated crawling and scraping face several challenges, including rate limits, IP restrictions, JavaScript-rendered content, and anti-bot protections.
Coverage is another obstacle. A dataset requires enough content across the topics and languages the model is expected to handle. Gaps in either can reinforce existing biases or leave blind spots in the model’s knowledge.
Responsible crawling also matters. You should limit request rates to avoid overloading websites, respect robots.txt and llms.txt, and follow applicable laws and website policies.
Data cleaning and preparation
Scraped web pages, usually stored as plain HTML files, are rarely ready for model training. They can contain navigation menus, cookie banners, advertisements, duplicated boilerplate, and other content that adds little value.
Data preparation removes unnecessary material, filters low-quality or harmful content, and identifies exact and near-duplicate documents. OpenAI’s public summaries of its training data describe quality filtering, deduplication, and safety filtering as standard steps before training.
Privacy is another consideration. PII (Personally Identifiable Information), such as email addresses and phone numbers, needs to be detected, removed, masked, or otherwise handled according to your project’s privacy requirements.
The cleaned data can then be converted into formats suited to its intended use. The output is a training-ready dataset, typically stored as clean text with source metadata retained for traceability. For language model training, that involves extracting text, splitting it into documents or training samples, and tokenizing it into units the model can process.
Continuous data collection
Facts change, products launch, events unfold, and laws are updated. A dataset collected once will soon become outdated, so you must refresh your training data regularly by collecting new content as it becomes available.
If the goal is to change a model’s learned behavior or capabilities, you should rely on additional training methods, such as fine-tuning. Alternatively, you can retrain the model on an updated dataset.
Real-time data retrieval: Beyond the training data cutoff
For information that has changed or wasn’t included in the training data, retrieving it from external sources is more practical than retraining the model.
Gemini supports grounding with Google Search. Similarly, Claude’s models and ChatGPT come with built-in web search tools. These integrations let AI systems search the web, retrieve current information, and generate answers grounded in verifiable sources.
A similar approach works with private or specialized content through RAG. Documents are split into smaller sections called chunks, converted into numerical representations called embeddings, and stored in a searchable index within vector databases.
When a user asks a question, the system retrieves the matching chunks and adds them to the model’s context. The model uses that information to generate an answer grounded in the fetched content. For reliable results, you should evaluate document relevance and reranking quality as covered in SuperAnnotate’s guide to RAG evaluation.
Where do ChatGPT, Claude, Gemini, and Google AI get their information?
AI model providers rarely disclose their training data sources in detail, but they often provide a high-level overview of the main sources.
Where does ChatGPT get its information?
OpenAI’s Help Center says its foundation models are built from publicly available data, data it obtains from third-party partners, and information that users, human trainers, and researchers provide or generate, along with synthetic data.
Where does Claude get its information?
Anthropic’s Transparency Hub describes training data per model. For Claude Sonnet 4.6, it lists public internet information, non-public third-party data, contractor/data-labeling data, opted-in user data, and internally generated data.
Where does Gemini get its information?
Google’s Gemini technical report mentions pretraining on web documents, books, and code, along with image, audio, and video data.
Where does Google AI get its information?
Most of the information comes from Google’s search results and indexed web pages, which Gemini models use to generate a summary.
Get training data and real-time web data for AI with Apify
AI systems need data at two stages: large, diverse datasets to train or fine-tune models, and fresh information for grounded responses. In most cases, that data comes from the web.
Building the infrastructure to fetch web data means managing browsers, proxies, retries, schedules, maintenance, storage, and monitoring. This can be complex and resource-intensive, especially when collecting data from multiple websites at scale.
Apify provides tools for extracting data from websites, e-commerce platforms, social media, and other online sources. Apify Store offers thousands of ready-to-run tools called Actors that automate data collection and automation tasks.
Collect web data for AI training
The Apify Actor Website Content Crawler performs a deep crawl of one or more websites and extracts text content and files from them. That’s a common first step when building a training corpus.
Other Actors collect data from specific platforms. For example, E-commerce Scraping Tool scrapes product details, prices, categories, reviews, and seller information from online retailers and marketplaces, including Amazon, Walmart, and eBay.
Actors take care of proxy rotation, JavaScript rendering, anti-bot measures, data parsing, website updates, and scalability. This lets you focus on data curation, quality checks, and model development. Results are stored in datasets that can be exported in formats such as JSON, JSONL, CSV, XML, and Excel.
Build real-time data pipelines for RAG and AI applications
Apify is a marketplace of tools for AI, as each Actor on Apify Store can be integrated into AI agents using the Apify MCP server, Apify Agent Skills, LangChain, LlamaIndex, Dify, n8n, and other integrations.
Actors can also be scheduled to feed fresh data into a knowledge base at regular intervals. For example, a competitive intelligence workflow might collect competitor pricing every morning and update a vector database that an AI-powered RAG application queries. The same approach works for market research, product monitoring, and internal knowledge updates.
Conclusion
So, where does AI get its information? For training, AI models learn from multiple sources, including web pages, books, code, research papers, synthetic data, and licensed datasets. For real-time grounding, AI systems retrieve information via web searches or knowledge bases through RAG pipelines.
Web data plays a central role in both processes. Turning web data into useful information for AI means collecting, cleaning, and transforming it for training or ingestion into a model’s context. Ready-to-run Actors on Apify handle that work for you, from collecting web data to keeping it fresh.

Frequently asked questions
How does AI learn from its training data?
Models learn statistical patterns from vast amounts of text. They repeatedly predict the next token, a word fragment, and adjust when wrong. Most documents aren’t stored word for word, though repeated text can be memorized.
Where does generative AI get its data from?
Generative AI models mainly learn from large collections of public web data. They also use books, academic papers, code, licensed datasets, and increasingly synthetic data. Providers disclose categories, not full lists, so the exact mix varies by model.
Does ChatGPT search the internet when you ask a question?
Yes, but only when search is active for that conversation, or when the model decides a question needs fresh information. Otherwise, ChatGPT answers from its training data. When it does search, it reads matching pages and usually links to its sources.
Where does Google AI get its information from?
Mostly from Google Search’s index. AI Overviews pull contextual pages from that index and summarize them with Gemini models.
Is my personal data being used to train AI models?
It can be, especially if your data is publicly available online (e.g., a public social media profile). Yet, AI providers typically filter personal information. To understand how your data is used, check the provider’s privacy policy. Also, look for account settings that let you opt out of having your conversations used for model training.
How does web scraping help collect AI training data?
Web scraping automatically gathers large amounts of text, images, and other content from websites. This gives AI models diverse, real-world data to learn from. It’s faster and cheaper than manual collection. The data still needs cleaning and legal checks.
How can you build AI solutions without an in-house engineering team?
Teams without in-house engineering expertise can work with an AI development partner to build AI applications and data pipelines. Directories such as SelectedFirms’ list of AI development companies in the UK help you shortlist potential partners by location and specialty.
What’s the difference between training data and search results?
Training data is what a model learned before release, and it’s fixed and static. Search results are retrieved when you ask, so they can be current. Training shapes how a model writes and reasons, while retrieval supplies facts the model may never have seen.
Can AI models forget or update their training data?
Removing specific information from a trained model is hard, and research on machine unlearning is still developing. Providers can retrain or fine-tune models on new data. Dynamic RAG is more practical because documents can be added or removed from a knowledge base at any time.
How does responsible data collection for AI work?
Responsible web data collection respects robots.txt and site terms, limits request rates, and honors copyright and licensing. It involves avoiding collecting personal data without a lawful basis, filtering out sensitive information before training, documenting where each dataset came from, and giving site owners a way to opt out.